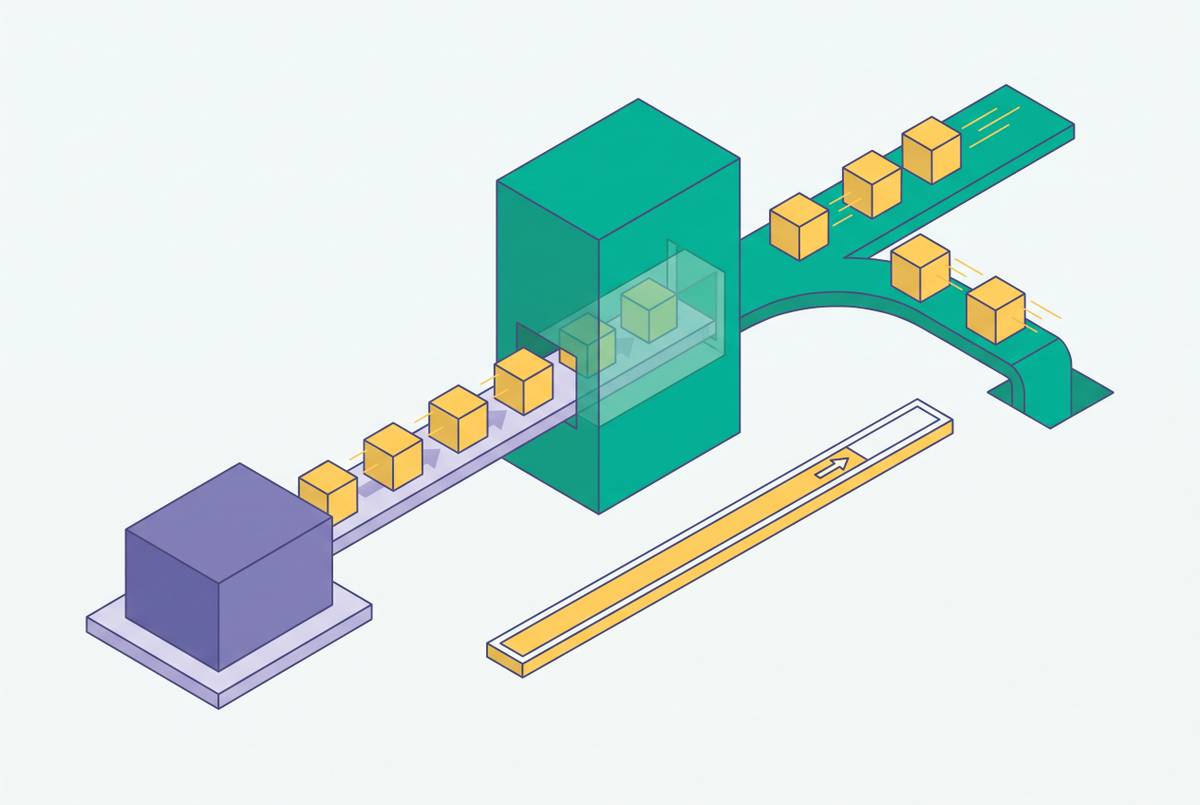
Speculative Decoding for Latency Reduction
A faster way to run large language models without sacrificing output quality.
Marcus Oyelaran
Contributing Editor, Long-Context & Research Frontiers
Marcus worked as a research scientist for several years before pivoting to editorial work, where he tracks preprints, replication efforts, and emerging techniques with a critical eye toward practical deployability. His background lets him bridge the gap between theoretical advances and the realities of running large models at scale.
1 story
A faster way to run large language models without sacrificing output quality.